APIFinTech · Financial operations
Invoice extraction that does not care what the invoice looks like
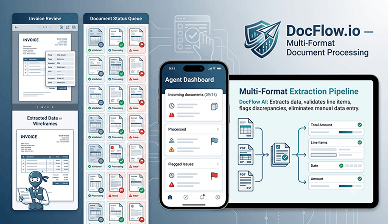
A document processing agent that reads invoices and contracts by understanding their content rather than matching their layout, with a deterministic validation layer that catches the errors the model would confidently miss.
لمحة سريعة
- المدة
- 13 أسبوعاً
- حجم الفريق
- 1 شخص
- نوع التعاقد
- بناء جديد
- نوع المشروع
- ذكاء اصطناعي وأتمتة
- القطاع
- التقنية المالية
الوضع
التحدي
Template-based OCR fails the moment a vendor changes their layout, and every new vendor means another rule. The goal was a system that reads content independent of presentation — while still being rigorous enough to spot a genuine error like a total that does not match its line items.
ما الذي فعلناه
Extraction by comprehension, verification by arithmetic. The model reads; deterministic code checks its work.
القرارات التي صنعت الفارق
Layout-agnostic extraction with structured schemas
Documents are converted to model-readable form, with vision processing for scanned PDFs, and prompts carry an explicit schema plus few-shot examples spanning layout variation. Understanding the document beats matching it.
Validation outside the model's control
Line-item totals, required fields and value ranges are checked in code, independent of the model's own confidence. A model that is confidently wrong is exactly the failure mode this has to survive, and self-reported confidence cannot catch it.
Route fields for review, not documents
Field-level confidence sends only uncertain fields to a human. Escalating the whole document because one line was ambiguous is how a system that works still fails to save anyone time.
ما الذي تغيّر
- reduction in manual entry
- 92%reduction in manual entry
- field-level extraction accuracy
- 98.4%field-level extraction accuracy
- average processing time per document
- <8saverage processing time per document
- of total and line-item mismatches caught
- 100%of total and line-item mismatches caught
- 92% — for routine invoice processing
- 98.4% — on the validation set
- 100% — by the validation layer, on the test set
92% less manual entry on routine processing, 98.4% field-level accuracy, under eight seconds per document, and every total or line-item mismatch in the test set caught before it reached a human.
الخدمات المستخدمة
- Layout-agnostic extraction pipeline with vision fallback
- Deterministic validation and discrepancy detection layer
- Field-level confidence routing and human review queue
- Serverless processing on Lambda with S3 document storage
ما الذي كنا سنفعله بشكل مختلف
لكل مشروع واحدة من هذه. ونشرها هو المقصد — فدراسة حالة بلا ندم فيها تسويق لا دليل.
The extraction quality was never the hard part. The validation layer was, because it is the thing that makes the output trustworthy enough to act on automatically. Next time that layer gets designed first and the prompting second.
أعمال أخرى
- Internet Money · Crypto financial services$10M+monthly transaction volume
One wallet interface across five blockchains
A multi-chain crypto platform where every chain hides behind one interface, with a tamper-evident audit trail underneath it. $10M+ moves through it monthly.
اقرأ دراسة الحالة - MagicTask · Project management SaaS100K+concurrent users
From latency spikes at 5,000 users to 100,000 concurrent
A gamified project management platform re-architected from a single Node server into an event-driven system that holds 100,000+ concurrent connections without the reward engine touching the critical path.
اقرأ دراسة الحالة